




Nvidia details Rubin architectural optimizations for inference – improvements target better performance and efficiency from the GPU to the rack
FLOPS are only the start
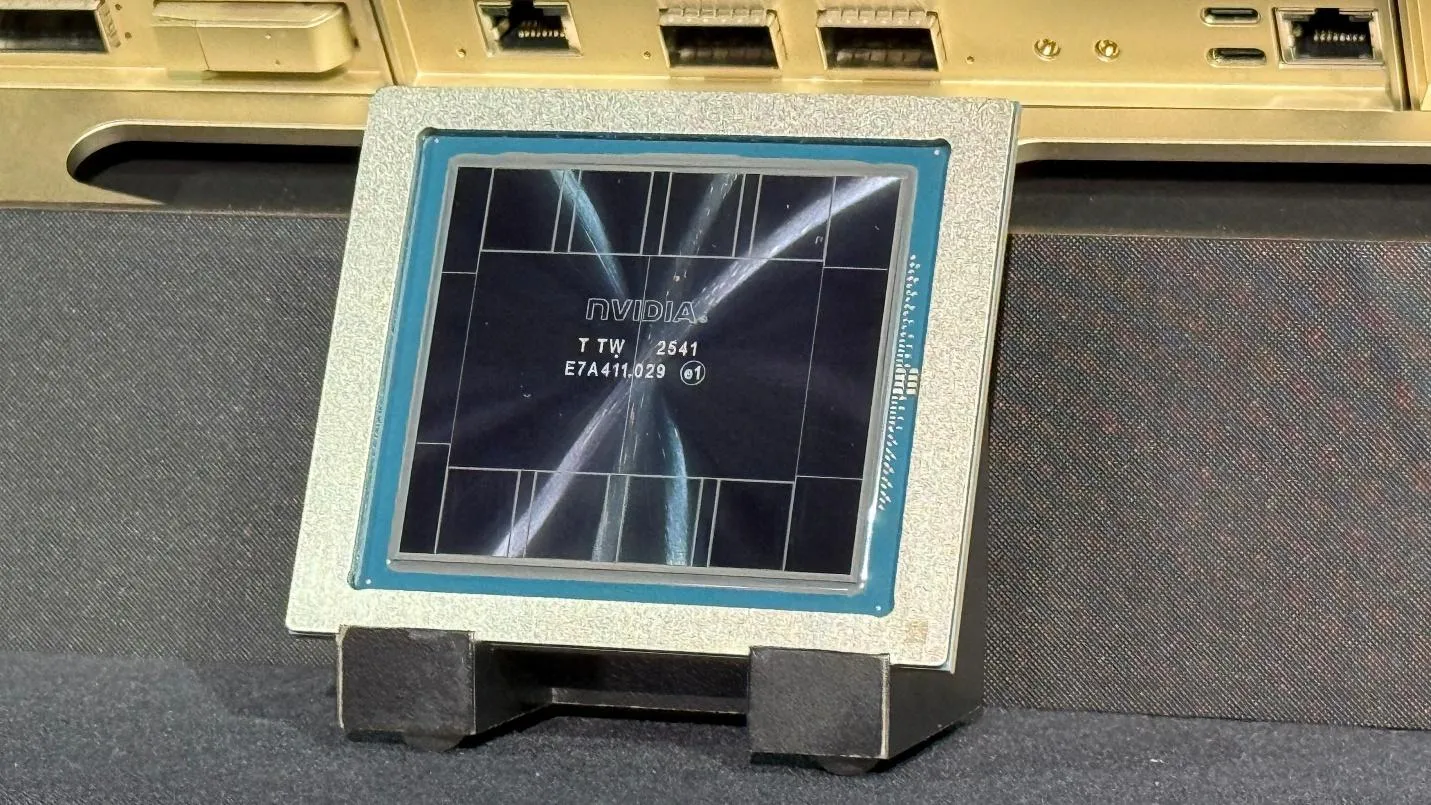
Nvidia's upcoming Vera Rubin platform, set to arrive later this year, will take the stage as the AI world shifts towards an era dominated not by frontier training runs but by the demands of agentic AI inference at massive scale. The hunger for generated tokens in agentic workflows and the demands of delivering them quickly, efficiently, and at low unit cost now dominate the discussion.
We’ve already gone in depth on new performance data around the Vera CPU and how it helps to accelerate agentic AI workloads, but that’s not all Nvidia is sharing today. It’s also detailing some new features of the Rubin architecture and how those features are meant to increase inference efficiency from the GPU level to rack-scale and data-center-scale implementations of this accelerator platform.
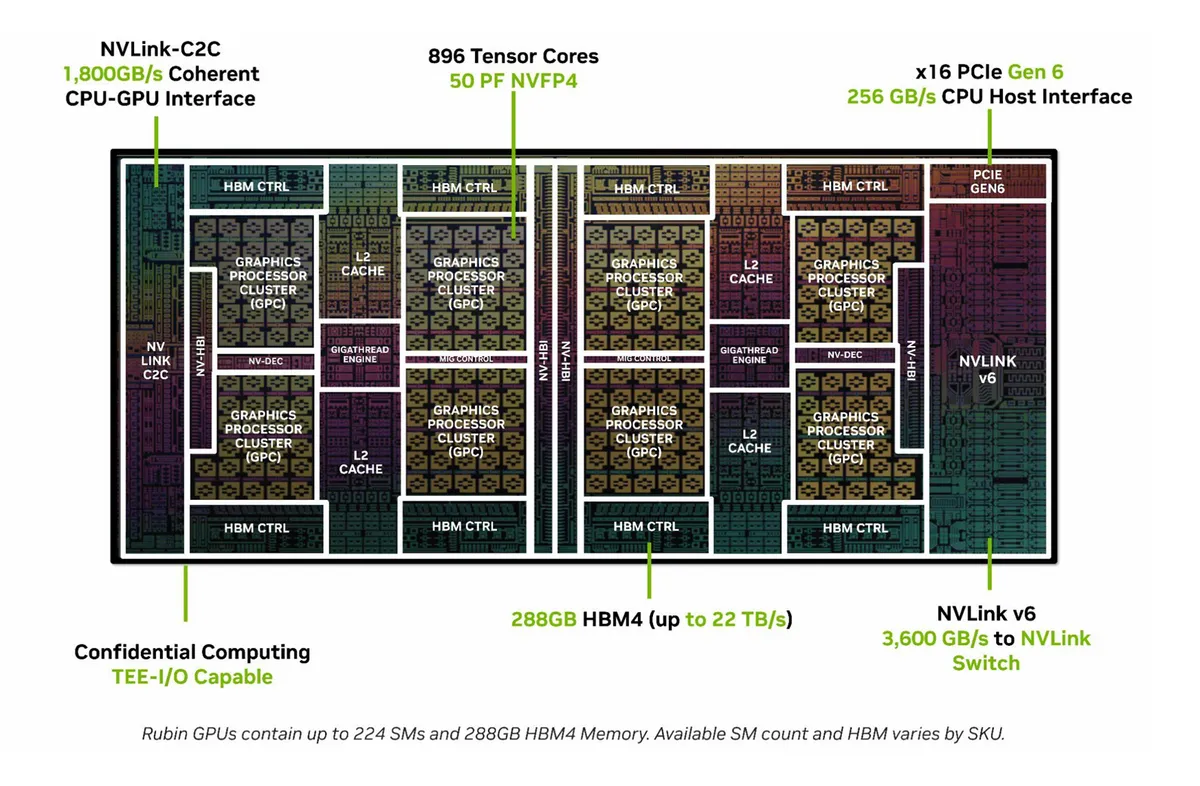
The full Vera Rubin NVL72 rack-scale system is built up from 36 Vera CPUs and 72 Rubin GPUs, but our focus today is on the GPU proper. Rubin joins two compute dies onto a single package using the Nvidia High Bandwidth Interface. The resulting chip offers 224 Streaming Multiprocessors (SMs) containing a total of 896 Tensor Cores alongside 288GB of HBM4 memory providing 22 TB/s of memory bandwidth.
As an inference-focused accelerator, Nvidia touts Rubin’s 50 sparse PFLOPS of NVFP4 inference throughput as its headline performance figure, although that’s only one of a dizzying array of data types this chip can handle. Here are some key rates to keep in mind for this chip so far:
Nvidia Rubin GPU |
Row 0 - Cell 1 |
NVFP4 Inference |
50 PFLOPS (with sparsity) |
NVFP4 Training |
35 PFLOPS |
FP8/FP6 Training |
17.5 PFLOPS |
INT8 |
250 TOPS |
FP16/BF16 |
4 PFLOPS |
TF32 |
2 PFLOPS |
FP32 |
130 TFLOPS |
FP64 |
33 TFLOPS |
Let’s dive into some of Rubin’s refinements for inference workloads to understand how Nvidia aims to keep all of those resources fully utilized.
The Rubin Tensor Memory Accelerator efficiently manages growing MoE models
First up, Nvidia highlights efficiency improvements in the Tensor Memory Accelerator (TMA) that help feed the Tensor Cores with data. The TMA is a dedicated engine built to handle memory address calculations and perform direct loads of array data into a GPU's shared local memory.
Leading AI model architectures have moved from dense models where every parameter is activated per output token to a mixture-of-experts (MoE) architecture where only certain specialized sub-networks are activated per token, based on the guidance of a router that helps judge which experts are best suited to processing a given input.
Get Tom's Hardware's best news and in-depth reviews, straight to your inbox.
MoE expert weights can be distributed across GPUs in order to efficiently utilize limited per-GPU HBM capacity. Nvidia says that Rubin's TMA has been improved to deal with the challenges of managing the growing numbers of experts in today’s leading models.
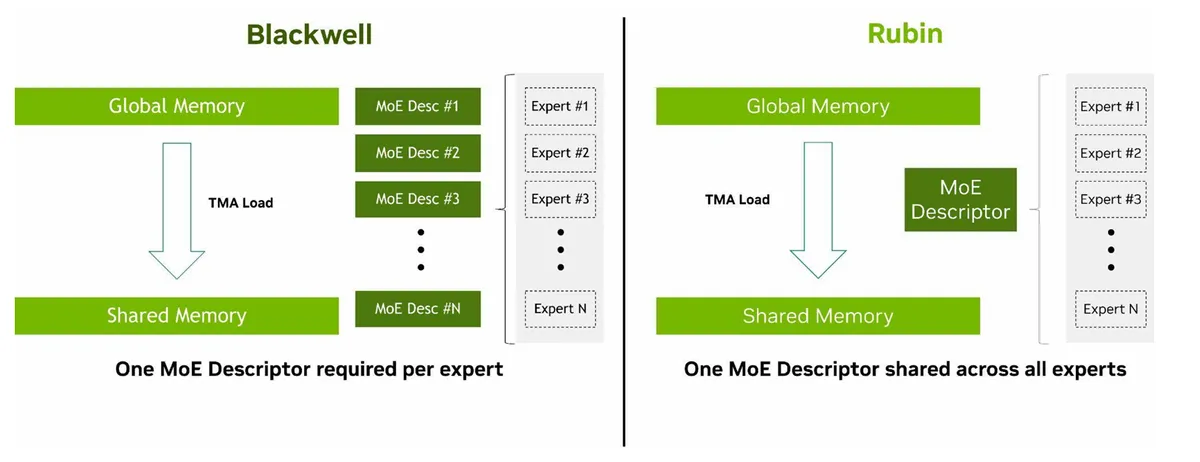
The TMA in Blackwell GPUs needed to maintain separate MoE descriptors in memory for the location of every expert, meaning that the overhead of locating and moving those expert weights requires more compute resources as the number of experts grows.
The Rubin TMA now supports GPU kernels that maintain and update a single unified MoE descriptor directly in the TMA instruction at runtime, reducing computation of MoE descriptor metadata and requiring less calculation overhead for data movement. This approach frees up GPU cycles for inference calculations, which is, of course, the place that you want your expensive AI accelerator spending the vast majority of its time.
Doubled K-dimension throughput, double the Tensor Core output
Rubin also improves the fundamental performance of matrix operations in the Tensor Core by doubling the amount of work those cores can perform on the K dimension, or the shared inner dimension of a pair of matrices to be multiplied. Without going too deep into the math, the size of the K dimension is directly related to the number of times the Tensor Core has to loop over the elements of the two matrices being multiplied.
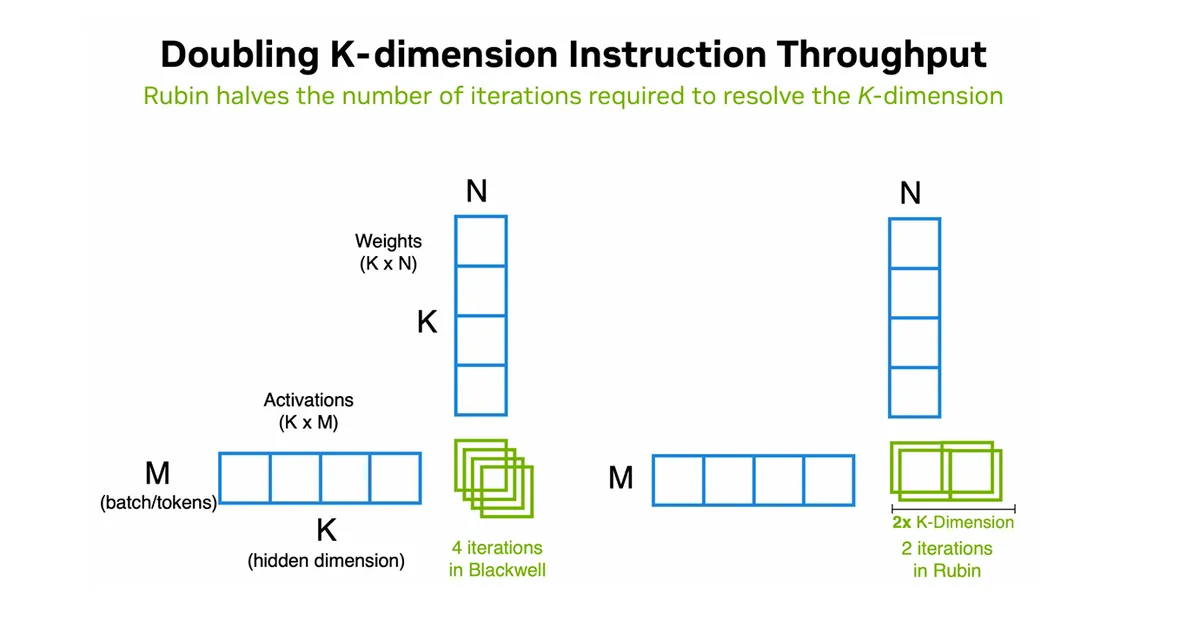
In Nvidia's example, then, the calculation of a result matrix that would require four loop iterations on Blackwell can be completed in only two on Rubin. Nvidia says this improvement has wide-ranging benefits for throughput-, memory-, and latency-bound kernels, and it’s helpful for both context processing and decode phases of inference.
Softmax on Rubin gets up to a 4X boost versus Blackwell
Rubin also focuses on improving the performance of the attention mechanism that’s foundational to transformer-based LLMs More advanced models now support context lengths of up to a million tokens, and quickly performing attention calculations on such long input sequences quickly is a key driver for improved inference performance.
Softmax is an essential operation in attention calculations, and in order to keep up with the improved Tensor Core throughput in Rubin, Nvidia has once again boosted softmax throughput in the GPU SM’s Special Function Unit (SFU).
Since it relies on the transcendental math capabilities of the SFU, softmax throughput can become a bottleneck for subsequent inference work, and it's a limitation that Nvidia already sought to address with enhancements to the Blackwell Ultra SFU. Blackwell Ultra doubled FP32 and BF16/FP16 exponential throughput compared to the first-gen Blackwell GB200.
GPU |
FP32 Exponential Throughput |
BF16/FP16 Exponential Throughput |
Blackwell |
1x |
1x |
Blackwell Ultra |
2x |
2x |
Rubin |
2x |
4x |
Rubin maintains Blackwell Ultra's 2X speedup over Blackwell in FP32 exponential math, and it doubles BF16/FP16 exponential calculations again compared to Blackwell Ultra, leading to a 4X improvement in throughput compared to Blackwell for those lower-precision data types.
Finer-grained dependency management, better Tensor Core occupancy
Rubin also increases Tensor Core occupancy by providing finer-grained opportunities for coordination between dependent kernels than on Blackwell. One case that Nvidia cites where these dependencies arise is the generation of activations for an LLM, where one kernel produces and stores data that is then used by a subsequent kernel as a prompt proceeds through a neural network.
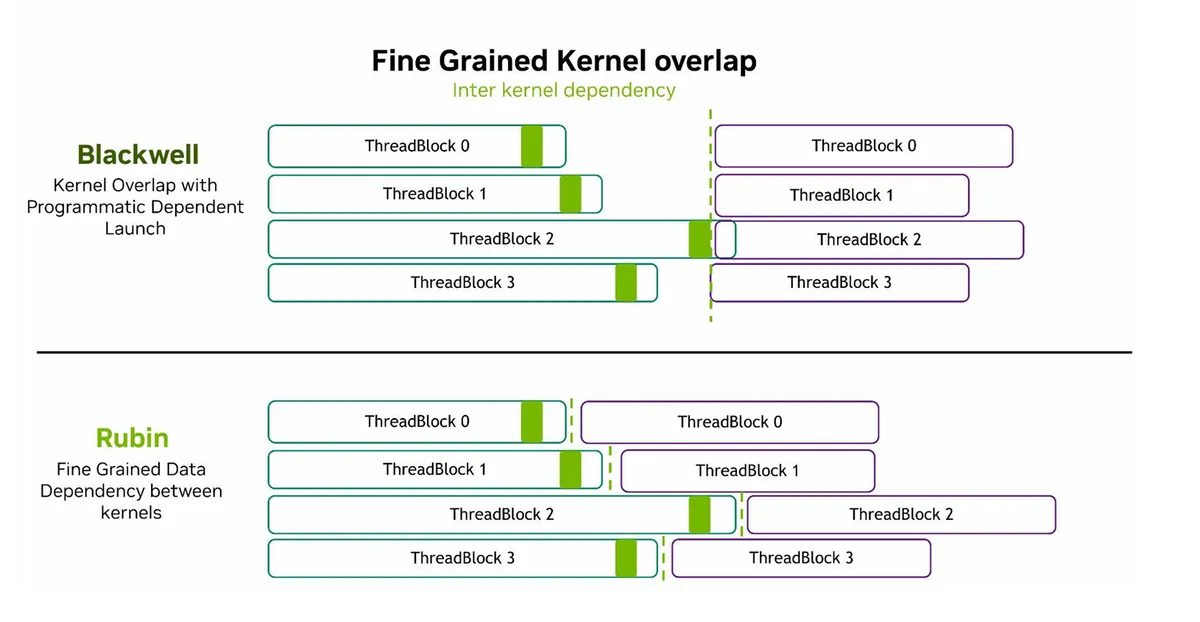
On Blackwell GPUs, a long-running producer kernel on one thread block (perhaps within a CUDA structure like a cluster) might delay the execution of a subsequent consumer kernel on those thread blocks, even as other thread blocks of the producer kernel have finished their work.
Rubin offers finer-grained dependency resolution between kernels, such that a consumer kernel can begin executing on individual thread blocks as soon as the producer kernel’s output from each thread block becomes available, instead of waiting for the entire batch of producer kernel data to become available. This finer-grained management results in better GPU utilization, lower kernel-to-kernel latency, and ultimately increases tokens per second per user.
More efficient inter-GPU communication, lower NVLink overhead
All of the improvements we've discussed so far relate to how work happens on one GPU, but the Vera Rubin NVL72 rack-scale accelerator comprises many GPUs connected over an NVLink fabric within the rack. Model weights, key-value cache data, and inter-GPU synchronization messages all move over this fabric, so keeping overhead and latency low is key to realizing maximum performance.
GPUs running CUDA kernels can directly initiate communication with other GPUs in the rack using Nvidia Collective Communications Library (NCCL) API, lowering overhead. Nvidia notes that because the GPU performs those operations directly as part of the compute kernel, the efficient execution of those communications becomes critical to performance.
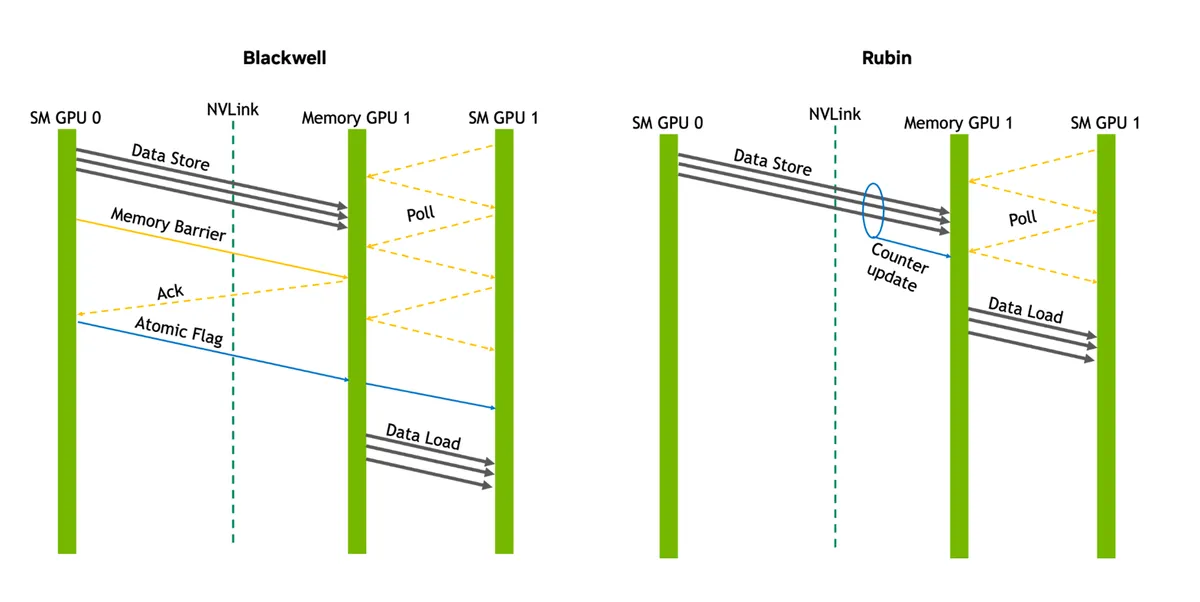
On a Blackwell system, an NVLink transfer between GPUs might require data store operations followed by a memory barrier and an atomic flag. The Rubin architecture introduces a feature called counted writes that reduces the amount of coordination and synchronization traffic necessary to share data between GPUs across the fabric.
On Rubin, the memory barrier and atomic operations are replaced by a single write counter update on the receiving GPU, reducing network traffic and latency and improving compute utilization by reducing the time spent waiting for coordination overhead.
All told, in tandem with the high single-threaded performance of the Vera CPU for agent harnesses, tool calling, code compilation, and more, the improvements in the Rubin GPU for performance on critical inference operations, as well as improved efficiency for data movement on-chip and across the rack, promise to help create a rack-scale and data-center-scale system that will both increase inference performance and lower per-token inference costs in the increasingly agentic future that Nvidia envisions. We’re excited to see more of what this GPU can do as deliveries of Vera Rubin systems are set to begin this fall.
Follow Tom's Hardware on Google News, or add us as a preferred source, to get our latest news, analysis, & reviews in your feeds.
As the Senior Analyst, Graphics at Tom's Hardware, Jeff Kampman covers everything that has to do with graphics cards, gaming performance, and more. From integrated graphics processors to discrete graphics cards to the hyperscale installations powering our AI future, if it's got a GPU in it, Jeff is on it.